Statements n quiz doubts

Please explain in brief:

1)The boundary becomes smoother with increasing value of K … i don’t understand how is smoothness determined?
2)In a KNN algorithm, can we put the value of k as an even number? --> is it because of the equality case when we won’t be able to predict our answer.
3)Euclidean distance treats each feature as equally important —> i didn’t understand what its trying to say.
4)k-NN is a memory-based approach is that the classifier immediately adapts as we collect new training data. Please explain

Hello @nikhil_sarda,

  1. Its always better to see than to hear. So for a dataset like this,
    image
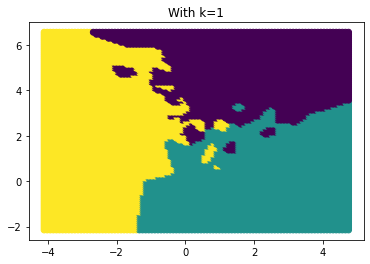
    The decision boundaries are as follows for different values of k.
    image
    image
    image
    image
    image
    image
    image
    image

As you can here see, the increasing values of k smoothes the decision boundary, smoothness can be defined as in terms of sudden abrupt changes in decisions when we move across the decision surface.
And i guess it evident above. Hope this clears your doubt.
The code for recreating the figures is here.

  1. Yes it is, infact you can put any value of k, be it odd or even, but as you said, for a even number, the voting can get equal and it would get ambiguos as to which class to predict in those scenerios.

  2. This pdf here can explain your question. (From slide 10). If you are still getting confused, continue in this thread.

  3. KNN calculates distances from all the available X instances. There is no parameters that the model learns given the dataset, like in Linear Regression for example. So as soon as a new instance arrives, KNN has to change nothing in its behaviour and can easily adapt to its new data, as it only calculates distance from all the data points available. But for a linear regression model, arrival of a new datapoint must be encorporated in the theta, for which we must retrain the whole model, if no online learning mechanism is imparted.

Hope this solves your doubts regarding KNN.

Happy Learning :slightly_smiling_face:

Thanks Sir I was also having same doubts

But sir this requires permission

Hello @Bhawna,

Can you recheck, I have changed the permission settings.

Yes Sir now it is working.

I still didn’t understand the 4 th , why is it called “memory” based approach?

After reading the pdf i have got some more doubts…

  1. What is cross validation?
  2. What i understood from the pdf is - that its unweighted distance for all points and hence its said that it treats all equally important and if its weighted then its unequal.Is it correct?
  3. What is noise…I had asked this doubt earlier but I was still not very sure how to say a datapoint a noise?
    4)Can we use the weight in the weighted eucledian as the weight function we have in LOWESS?

Basically a memory based approach is a method in which you need the full data to be loaded in the memory while a model based approach doesnt need it. A model based approach learns parameters from the data and only keeps it for inference. In KNN, the entire data is necessary to predict for a new instance, hence, a memory based model.

Cross Validation is a technique which involves reserving a particular sample of a dataset on which you do not train the model. Later, you test your model on this sample before finalizing it. Basically, you can simply take it as splitting the training data into train data and validation data to have an approximate idea as to how the model will perform to unseen datasets. More can be found here.

Yes

Check this out.

Basically the idea of weighted eucledian and the weight function in LOWESS is same. The weighted function in LOWESS basically is an exponential decay function, meaning, the points closer will have more value and it will decrease exponentially as we move further away. This idea wont make much sense in the euclidean scenerio. Why? Because we dont have a reference feature to calculate the value of weighted function(if you have then you sure can use the exact same). Also, in most of the cases you never will have a order and scale in which the features lie in the feature space. If so, then what can be a way of putting weights in for a euclidean distance. You can do something like,

w = 0.2 # 0 <= w <= 1
d(x, y) = sqrt(sum(w*x**2 + (1- w)*y**2))

The above is only an example, you can use any arbitrary weights according to your prior belief about the features.

Happy Learning :slightly_smiling_face:

I hope I’ve cleared your doubt. I ask you to please rate your experience here
Your feedback is very important. It helps us improve our platform and hence provide you
the learning experience you deserve.

On the off chance, you still have some questions or not find the answers satisfactory, you may reopen
the doubt.